The Machine That Answers
What changes when a machine can answer in our own language, and how should we decide how far to trust it?
For seventy years, artificial intelligence meant teaching machines rules. The systems that finally learned to talk did it by predicting the next word across most of the written internet. The result answers almost any question fluently, is right often enough to be useful and wrong often enough to be dangerous, and asks every organisation the same old question in a new form, which is when to trust a source you cannot check.
For people who build products
Decisions worth studying
12 decisions from this history, each with the situation, the alternatives, what happened and a verdict. Open one for the full case. The verdict says how a decision turned out, which is not the same as whether it was wise; see moral luck.
-
Publish the Transformer architecture openly, in keeping with academic norms Publishing a breakthrough is a strategic choice; if you share the idea, your advantage has to come from how fast you turn it into a product.
- Situation
- Google researchers had found a simpler, highly parallel way to model language that trained far faster on modern chips.
- Alternatives
- Keep the design proprietary and build products on it internally first.
- What happened
- The paper became the foundation of nearly every large language model, including those of Google’s competitors. Google kept a strong research position but was not the first to turn it into a mass product.
- Verdict
- Open publication attracted talent and set the agenda for the field, and it also handed rivals the core idea. The commercial cost came less from publishing than from the slower decision to ship.
Open standards out-reach closed gardensIncumbents absorb the challenger’s best idea
-
Withhold the full GPT-2 model over misuse concerns and release it in stages When a risk is new and hard to measure, a reversible, staged release buys information cheaply.
- Situation
- A text generator could produce plausible fake news. No norms existed for releasing such models.
- Alternatives
- Release everything at once, as was usual in research, or never release the large model.
- What happened
- The full model was published nine months later. OpenAI reported no clear evidence of misuse by then, and outside groups had replicated similar models.
- Verdict
- The specific risk was overstated, but the decision created the practice of staged, monitored release that later became standard.
-
Release a free chat interface to an existing model as a “research preview” The interface that lets ordinary people try a capability can matter more than the next improvement in the capability.
- Situation
- GPT-3.5 was already available to developers through an API. Most of the public had never used it.
- Alternatives
- Keep selling through the API to businesses, or wait for a more capable and polished model.
- Numbers
- An estimated 100 million monthly users within about two months (UBS, from Similarweb data).
- What happened
- ChatGPT became the fastest-growing consumer application then recorded and redrew the strategy of every large technology company.
- Verdict
- The model was not new. The decision to give it a familiar interface, free, and to learn from public use was what made it a product.
A small working thing beats a grand designUsers decide what the product is forDistribution beats elegance
-
Announce a public chatbot quickly in response to ChatGPT, with a promotional demonstration When the known flaw of a technology is that it is confidently wrong, the launch itself must be checked against that flaw.
- Situation
- Google faced pressure to show it was not falling behind in the technology its own researchers had pioneered.
- Alternatives
- Wait until the product had been tested more thoroughly, or integrate AI more gradually into search.
- Numbers
- Alphabet lost about $100 billion in market value on 8 February 2023, after a promotional answer about the James Webb telescope was found to be wrong.
- What happened
- The episode damaged confidence at the time. Google later rebuilt its consumer AI as Gemini and integrated it widely across its products.
- Verdict
- Responding was necessary; demonstrating an unchecked answer in public was not. Speed was chosen over verification in a product whose main weakness was accuracy.
-
Release capable language models with downloadable weights that others could run and modify If a technology complements your business rather than being it, giving it away can weaken competitors more than selling it would strengthen you.
- Situation
- Meta was behind OpenAI and Google in chat products but did not sell AI access as its main business.
- Alternatives
- Keep the models closed and sell access through an API.
- What happened
- Llama became the base for a large ecosystem of open models, pulled down the price of capability, and helped establish open weights as a serious alternative.
- Verdict
- Making a rival’s product cheaper is a coherent strategy when it is not your business, and it worked as ecosystem-building. It did not by itself give Meta the leading model.
Open standards out-reach closed gardensWho pays shapes what gets built
-
Let a website chatbot answer policy questions, then argue in a dispute that the chatbot was responsible for its own words Whatever your AI says to customers, you have said.
- Situation
- A customer relied on the chatbot’s incorrect description of a bereavement fare refund.
- Alternatives
- Limit the chatbot to verified policy text, or honour the advice and correct the system.
- Numbers
- The tribunal ordered a partial refund plus interest and fees: a small sum, widely reported.
- What happened
- The British Columbia Civil Resolution Tribunal held the airline responsible for all information on its website, chatbot or not.
- Verdict
- The financial stake was tiny; the reputational cost and the precedent were not. A company cannot separate itself from the voice it deploys.
-
Replace much of customer service with an AI assistant, then reverse course and hire people again Measure AI on the cases that matter most, not on the share of cases it can close.
- Situation
- The company had frozen hiring and announced that its assistant was doing the work of 700 agents within a month of launch.
- Alternatives
- Use AI to route and draft answers while keeping people responsible for the harder conversations.
- Numbers
- Klarna said the assistant handled two-thirds to three-quarters of chats, about 2.3 million conversations, in its first month.
- What happened
- In 2025 the company’s chief executive said cost had been “too predominant” in the evaluation and that quality had suffered, and Klarna began recruiting human agents again.
- Verdict
- Volume and cost were measured; quality on the hardest cases was not. The company corrected the decision publicly, which is to its credit.
-
Release a strong reasoning model openly, with a technical report emphasising low training cost In a market that assumes scale is the only advantage, a credible demonstration of efficiency can move more than a better product.
- Situation
- Export controls limited Chinese access to the most advanced chips, and leading Western models were closed.
- Alternatives
- Keep the model proprietary and sell access.
- Numbers
- Nvidia lost about $589 billion of market value on 27 January 2025, the largest one-day loss in US stock-market history.
- What happened
- The release narrowed the perceived gap between open and closed models and pushed rivals to cut prices and release reasoning models more widely.
- Verdict
- Openness turned a technical result into global attention and a change in industry pricing. The cost figures were debated, but the strategic effect was not.
Open standards out-reach closed gardensHiding the machine wins once the machine is cheap
-
Turn a quiz-show demonstration into a business unit aimed at cancer care and other high-stakes fields A general capability does not become a solution until it fits the data, workflow and accountability of a specific job.
- Situation
- Watson had beaten two Jeopardy! champions on television, and IBM sought a new growth business.
- Alternatives
- Keep Watson as a research platform, or start with narrow, lower-stakes uses and expand as the technology matured.
- Numbers
- One flagship oncology project with MD Anderson cost about $62 million by 2016 and, according to a university audit, was not in clinical use.
- What happened
- Watson Health struggled to fit into real clinical workflows. IBM sold most of its assets in 2022.
- Verdict
- The demonstration was real; the leap from a game with clear answers to medicine, with messy data and professional judgement, was underestimated.
-
Put an OpenAI model into its search engine within weeks of ChatGPT’s launch, then cap conversations when it misbehaved A challenger can afford public experiments that an incumbent cannot; plan the limits you will add before you need them.
- Situation
- Microsoft saw a rare chance to challenge Google in search using a partner’s model.
- Alternatives
- Wait for the model to be more thoroughly tested in long conversations.
- Numbers
- Within days, conversations were limited to 5 turns per session and 50 per day, then relaxed within a week.
- What happened
- Bing gained attention but not a large share of search. The partnership made Microsoft the leading distributor of OpenAI’s models across its products.
- Verdict
- Shipping early and correcting quickly was a defensible bet for a challenger with little to lose in search; the larger payoff came in Office and developer tools.
Decide at the speed of reversibilityDistribution beats elegance
-
Add a reward for users’ immediate thumbs-up reactions to the main ChatGPT model, then roll it back If you optimise a product for momentary approval, it will learn to flatter.
- Situation
- Companies tune assistants on feedback to make them more helpful.
- Alternatives
- Weight long-term satisfaction and accuracy more heavily than immediate approval.
- What happened
- The update made the model excessively flattering. OpenAI reversed it within days and published an explanation.
- Verdict
- An immediate-approval metric rewarded pleasing over helping. The quick, public correction was the right response.
-
Test advertising in ChatGPT for free and low-priced tiers When a product that answers questions takes advertising, its credibility depends on keeping the two visibly separate.
- Situation
- Serving hundreds of millions of free users was expensive, and subscriptions covered only part of the cost of the frontier.
- Alternatives
- Keep the free tier ad-free and rely on subscriptions and business sales.
- What happened
- Ads began appearing in the United States in February 2026, labelled and kept apart from answers and from sensitive topics.
- Verdict
- A familiar route to paying for a free product at scale; whether answers stay independent of advertisers is the test still to come.
In 1950 Alan Turing opened a paper in the philosophy journal Mind with a sentence that has been argued over ever since: “I propose to consider the question, ‘Can machines think?’”1 He immediately set it aside. The words “machine” and “think” were too vague, he said, and a definition based on how people use them would turn the question into an opinion poll. Instead he proposed a game. If a machine, conversing in text, could not be told apart from a person, the old question would lose most of its interest.
For seventy years the game was a thought experiment. Then, quite suddenly, it was a product. Since late 2022 hundreds of millions of people have typed questions into a box and received fluent, organised, often useful answers. Many of them could not reliably say whether a person or a machine had written what they read, and many no longer cared. Turing’s game was passed without a ceremony, mostly by people asking for help with emails.
This essay is about the large language model: what it is, how it came to work, why it works the way it does, and what it asks of the people and organisations that rely on it. Its history contains one of the most instructive reversals in technology. The approach that finally produced machines that could converse was close to the opposite of the one the field’s founders believed in. And its main practical problem is one of the oldest problems in philosophy: when, and how much, to trust what you are told.
The world before the question
Long before anyone built a computer, people imagined machines that could reason. Gottfried Wilhelm Leibniz, in the 1670s and 1680s, dreamed of a characteristica universalis, a symbolic language in which every concept could be written, and a calculus ratiocinator that would let disputes be settled by calculation. “Let us calculate,” he imagined philosophers saying to each other instead of arguing. George Boole’s The Laws of Thought (1854) reduced logical reasoning to algebra. Gottlob Frege and Bertrand Russell tried to rebuild mathematics on pure logic. Behind all of this lay one hope: that thinking, at bottom, was the manipulation of symbols according to rules.
The opposite hope also has a long history, though it was usually stated by sceptics. Ada Lovelace, writing in 1843 about Charles Babbage’s Analytical Engine, observed that the machine “has no pretensions whatever to originate anything. It can do whatever we know how to order it to perform.” A century later Turing devoted a section of his 1950 paper to “Lady Lovelace’s Objection,” and his answer looked forward to what eventually happened. A machine that learned, he suggested, might come to do things its programmers had not foreseen. He even proposed building a “child machine” and educating it, rather than trying to program an adult mind directly.1
The two ideas, intelligence as rules written down and intelligence as something learned from experience, run through the entire history that follows. For most of seventy years the first was dominant. The large language model is the triumph of the second.
Naming a field: Dartmouth and the symbolic programme
In the summer of 1956 a small group of researchers met at Dartmouth College for a workshop that gave the field its name. The proposal, written the previous year by John McCarthy, Marvin Minsky, Nathaniel Rochester and Claude Shannon, stated its premise plainly: the study would proceed “on the basis of the conjecture that every aspect of learning or any other feature of intelligence can in principle be so precisely described that a machine can be made to simulate it.”2 It also predicted that “a significant advance” could be made on these problems if a carefully selected group worked on them “together for a summer.”
That confidence shaped the next three decades. At the workshop itself, Allen Newell and Herbert Simon showed the Logic Theorist, a program that proved theorems from Russell and Whitehead’s Principia Mathematica. They followed it with the General Problem Solver, which attacked puzzles by comparing where it was with where it wanted to be and choosing steps to close the gap. McCarthy created Lisp in 1958, a programming language for manipulating symbols that became the field’s working tool for a generation. In 1957 Simon predicted that within ten years a computer would be world chess champion. It took forty.
The symbolic programme had a coherent philosophy. Newell and Simon later stated it as the “physical symbol system hypothesis”: a system that manipulates symbols has the necessary and sufficient means for general intelligent action. If that was true, the work of AI was to find the right symbols and the right rules. Language, in this view, was a formal system like logic. To understand a sentence was to translate it into a representation a machine could reason over.
Early successes encouraged the view. Terry Winograd’s SHRDLU (1970) conversed sensibly about a simulated world of coloured blocks, answering questions and carrying out commands such as “pick up a big red block.” But the blocks world was tiny and fully specified. Every attempt to scale the approach to the open-ended world foundered on the same problem: there was always more knowledge needed than anyone had written down.
The first spring of learning machines
The rival idea arrived almost at once. In July 1958 the US Navy held a press demonstration of the perceptron, designed by the psychologist Frank Rosenblatt at Cornell. Running on an IBM 704, it learned to tell left from right after fifty trials. The wire report of the event described it as “the embryo of an electronic computer” that the Navy expected would “be able to walk, talk, see, write, reproduce itself and be conscious of its existence.”3 Rosenblatt’s own claims were more cautious than the coverage, but the promise was set: here was a machine that learned from examples rather than being told rules.
The perceptron was a single layer of adjustable connections, loosely modelled on neurons. It could learn to separate patterns that a straight line could divide, and nothing more. In 1969 Minsky and Seymour Papert published Perceptrons, a rigorous mathematical analysis that proved these limits, including the perceptron’s inability to learn a simple “exclusive or.” They suspected that multi-layer networks would share similar problems, though they could not prove it. The book is often blamed for a decade-long collapse of interest in neural networks. The truth is more complicated, since funding was moving toward symbolic AI already, but the effect was real. The learning tradition went quiet.
Winters and rules
By the early 1970s the promises of the symbolic programme had run far ahead of its results. Machine translation, heavily funded in the United States during the Cold War, had been judged a disappointment by a government advisory committee as early as 1966. In 1973 a review for the British Science Research Council by the mathematician James Lighthill concluded that AI had largely failed to deliver on its promises and that its methods broke down under the “combinatorial explosion” of possibilities in real problems. Funding in Britain fell sharply, and US agencies became more demanding at about the same time. This was the first of what came to be called “AI winters.”
In the 1980s the rules returned in commercial form. Expert systems captured the knowledge of specialists as hundreds or thousands of if-then rules. MYCIN, built at Stanford in the 1970s, recommended antibiotics for blood infections about as well as specialists in tests, though it was never used clinically. XCON, built for Digital Equipment Corporation, configured computer orders and was credited with large savings. Companies set up “knowledge engineering” departments to interview experts and write down what they knew. In 1982 Japan’s Ministry of International Trade and Industry launched the Fifth Generation Computer Systems project, a ten-year national effort, eventually costing more than ¥50 billion, to build machines for logical inference.4 Alarmed governments in the US and Britain answered with programmes of their own. An industry of specialised Lisp machines grew up to run AI software.
The boom ended as the first had. Expert systems were costly to build and harder to maintain: every change in the world required a knowledge engineer to rewrite rules, and the rules interacted in ways nobody could foresee. They were brittle at the edges, failing badly on cases slightly outside what they had been told. Ordinary workstations became powerful enough to run Lisp, and the specialised machine market collapsed in the late 1980s. The Fifth Generation project closed in the early 1990s having advanced logic programming but without the intelligent machines it had promised. A second winter followed.
The lesson the field drew at the time was that intelligence needed vastly more knowledge. One project, Cyc, begun by Douglas Lenat in 1984, set out to write down common sense itself, millions of facts such as “water is wet” and “people cannot be in two places at once.” It continued for decades. Its very scale was a kind of evidence: the knowledge people use without noticing seemed to have no end.
The machine that only talked
Running alongside these programmes was a small, unsettling experiment. In 1966, at MIT, Joseph Weizenbaum wrote a program called ELIZA. Its most famous script imitated a psychotherapist by turning a user’s statements back into questions: tell it you were unhappy and it would ask why you were unhappy. It understood nothing. It matched patterns and rearranged words.
People responded to it as if it understood. Weizenbaum later recounted that his secretary, who had watched him build the program, asked him to leave the room so she could talk to it in private. He wrote that he had not realised “that extremely short exposures to a relatively simple computer program could induce powerful delusional thinking in quite normal people.”5 Some psychiatrists suggested that programs like it might one day provide therapy at scale. The experience turned Weizenbaum into one of the field’s most serious critics. In Computer Power and Human Reason (1976) he distinguished between deciding, which is computational, and choosing, which is a matter of judgement, and argued that some choices should never be handed to machines, not because machines could not produce an answer but because the choice required a person who could be responsible for it.
ELIZA established two facts that remain central to this day. Fluent language is a powerful signal of a mind, so powerful that people supply understanding a system does not have. And the question of what a machine should do cannot be settled by asking what it can do.
Learning returns, quietly
The learning tradition never disappeared. In 1986 David Rumelhart, Geoffrey Hinton and Ronald Williams published a paper in Nature that popularised backpropagation, a way to train networks with many layers by calculating how much each connection contributed to an error and adjusting it slightly.6 It answered the challenge Minsky and Papert had posed: multi-layer networks could learn functions a single layer could not. In the same years, Yann LeCun used similar networks to read handwritten digits on bank cheques, one of the first commercial uses of neural networks. Through the 1990s and 2000s, however, other statistical methods, such as support vector machines, usually performed better, and neural networks were again unfashionable. A small group of researchers, among them Hinton, LeCun and Yoshua Bengio, kept working on them with modest funding. In 2018 the three shared the Turing Award for that persistence.
Language had its own statistical tradition, and it was here that the practical turn came first. In his 1948 paper founding information theory, Shannon showed that English could be approximated by predicting each letter or word from the ones before it, and generated passages of increasingly English-like nonsense to demonstrate it. The idea that language could be modelled as probabilities, rather than rules, lay dormant for decades in linguistics, which under Noam Chomsky’s influence treated grammar as a formal system of rules and dismissed probabilistic models of sentences as beside the point.
Engineers working on speech recognition at IBM in the 1970s and 1980s took the probabilistic path anyway, and it worked better. A remark attributed to the group’s leader, Frederick Jelinek, became famous in the field: every time he fired a linguist, the performance of the speech recogniser went up. Whether or not he said it in those words, it captured a real shift. In the early 1990s IBM researchers applied the same statistical approach to translation, learning which words and phrases corresponded from millions of sentences of Canadian parliamentary records published in both English and French. Statistical translation steadily overtook rule-based systems.
Google, with more text than anyone had ever assembled, became the strongest advocate of this view. In 2009 three of its researchers, Alon Halevy, Peter Norvig and Fernando Pereira, published an essay titled “The Unreasonable Effectiveness of Data,” a play on a famous essay about mathematics in physics. Their advice to researchers, in effect, was to stop trying to write elegant theories of language and to “follow the data”: simple models trained on very large amounts of text outperformed sophisticated models trained on less.7 Google Translate, launched in 2006, was built on exactly that principle.
Watson: the last great system of the old kind
In February 2011, IBM’s Watson defeated two of the most successful champions of the quiz show Jeopardy! on television. It was an extraordinary engineering achievement that combined hundreds of techniques: statistical search across vast stores of text, hand-built rules, and methods for weighing the evidence for competing answers. It was also, in retrospect, the culmination of an approach that was about to be overtaken.
IBM made a consequential decision after the victory. Rather than treat Watson as a research platform, it built a business unit around it and aimed it at the hardest commercial problems, notably cancer care. One of the most visible projects, with the University of Texas MD Anderson Cancer Center, was intended to advise oncologists and match patients to clinical trials. By 2016 it had cost about $62 million, and a university audit found that the system was not in clinical use; the audit pointed largely to project management and integration problems, including the system’s incompatibility with the hospital’s new electronic records, and IBM maintained that the pilot had succeeded technically.8 Across the industry, Watson Health became a symbol of the gap between a dramatic demonstration and the messy work of fitting a system into a real institution. IBM sold most of the Watson Health assets in 2022.
The lesson for decision-makers was not that the technology was useless, but that a general-purpose capability, marketed as a solution to a specific, high-stakes problem, will meet all the difficulty of that problem: its data, its workflows, its regulation and its professional judgement. The same lesson would return with generative AI a decade later.
Deep learning wins
The turning point came in 2012. A deep neural network trained on graphics processors by Alex Krizhevsky, Ilya Sutskever and Geoffrey Hinton, later known as AlexNet, won the ImageNet image recognition competition with an error rate far below that of rivals relying on features designed by experts. Three things had changed since the 1980s: there was far more data, thanks to the internet; chips made for video games turned out to be ideal for the arithmetic of neural networks; and researchers had accumulated many small techniques that made deep networks trainable.
The technology companies moved quickly. Google hired Hinton and his students in 2013. In 2014 it bought DeepMind, a London laboratory founded to pursue general intelligence, for a price widely reported at around $500 million. Facebook founded an AI research lab led by LeCun. Within a few years, learned systems led in image recognition, speech recognition and translation; Google replaced its statistical translation system with a neural one in 2016. In March 2016 DeepMind’s AlphaGo defeated Lee Sedol, one of the world’s strongest players of Go, a game long thought too intuitive for machines. One of its moves, the 37th in the second game, was so unusual that commentators at first took it for a mistake.
Language came next. In 2013 Tomas Mikolov and colleagues at Google released word2vec, which represented each word as a list of numbers learned from the contexts it appeared in. Words used in similar ways ended up close together, and some relationships appeared as directions: the vector arithmetic “king minus man plus woman” landed near “queen.” Meaning, or something like it, had emerged from patterns of use. In 2014 and 2015 researchers introduced networks that read a sentence in one language and wrote it in another, and the “attention” mechanism, which let the network look back at the relevant words of the input as it produced each word of the output.
The reinforcement-learning researcher Rich Sutton later summarised what all of this showed in a short essay called “The Bitter Lesson” (2019). It begins: “The biggest lesson that can be read from 70 years of AI research is that general methods that leverage computation are ultimately the most effective, and by a large margin.”9 The lesson was bitter, Sutton wrote, because researchers repeatedly built their own understanding of a problem into their systems, enjoyed short-term gains, and were then overtaken by methods that simply learned more from more data. The Dartmouth conjecture assumed intelligence would be described. The systems that worked were never given the description. They found their own.
A laboratory built for a race
In December 2015 a group including Sam Altman, Elon Musk, Ilya Sutskever and Greg Brockman founded OpenAI as a nonprofit research laboratory, with pledges of $1 billion. Its stated purpose was to ensure that artificial general intelligence, if it arrived, benefited all of humanity, and its founding concern was that the technology might otherwise be controlled by a single company, which at the time meant Google. The organisation was born, in other words, out of a theory of competition: that the safest course was to be at the frontier rather than to stand aside.
That theory has shaped the industry ever since. Each new laboratory was founded partly in reaction to an earlier one. Anthropic was founded in 2021 by former OpenAI researchers, including Dario and Daniela Amodei, who wanted a stronger focus on safety research, and was organised as a public benefit corporation. Elon Musk, who left OpenAI’s board in 2018, founded xAI in 2023. The pattern is a recurring one in this history: the belief that a technology is dangerous has accelerated its development, because each group concluded that it should be the one to build it.
Attention is all you need
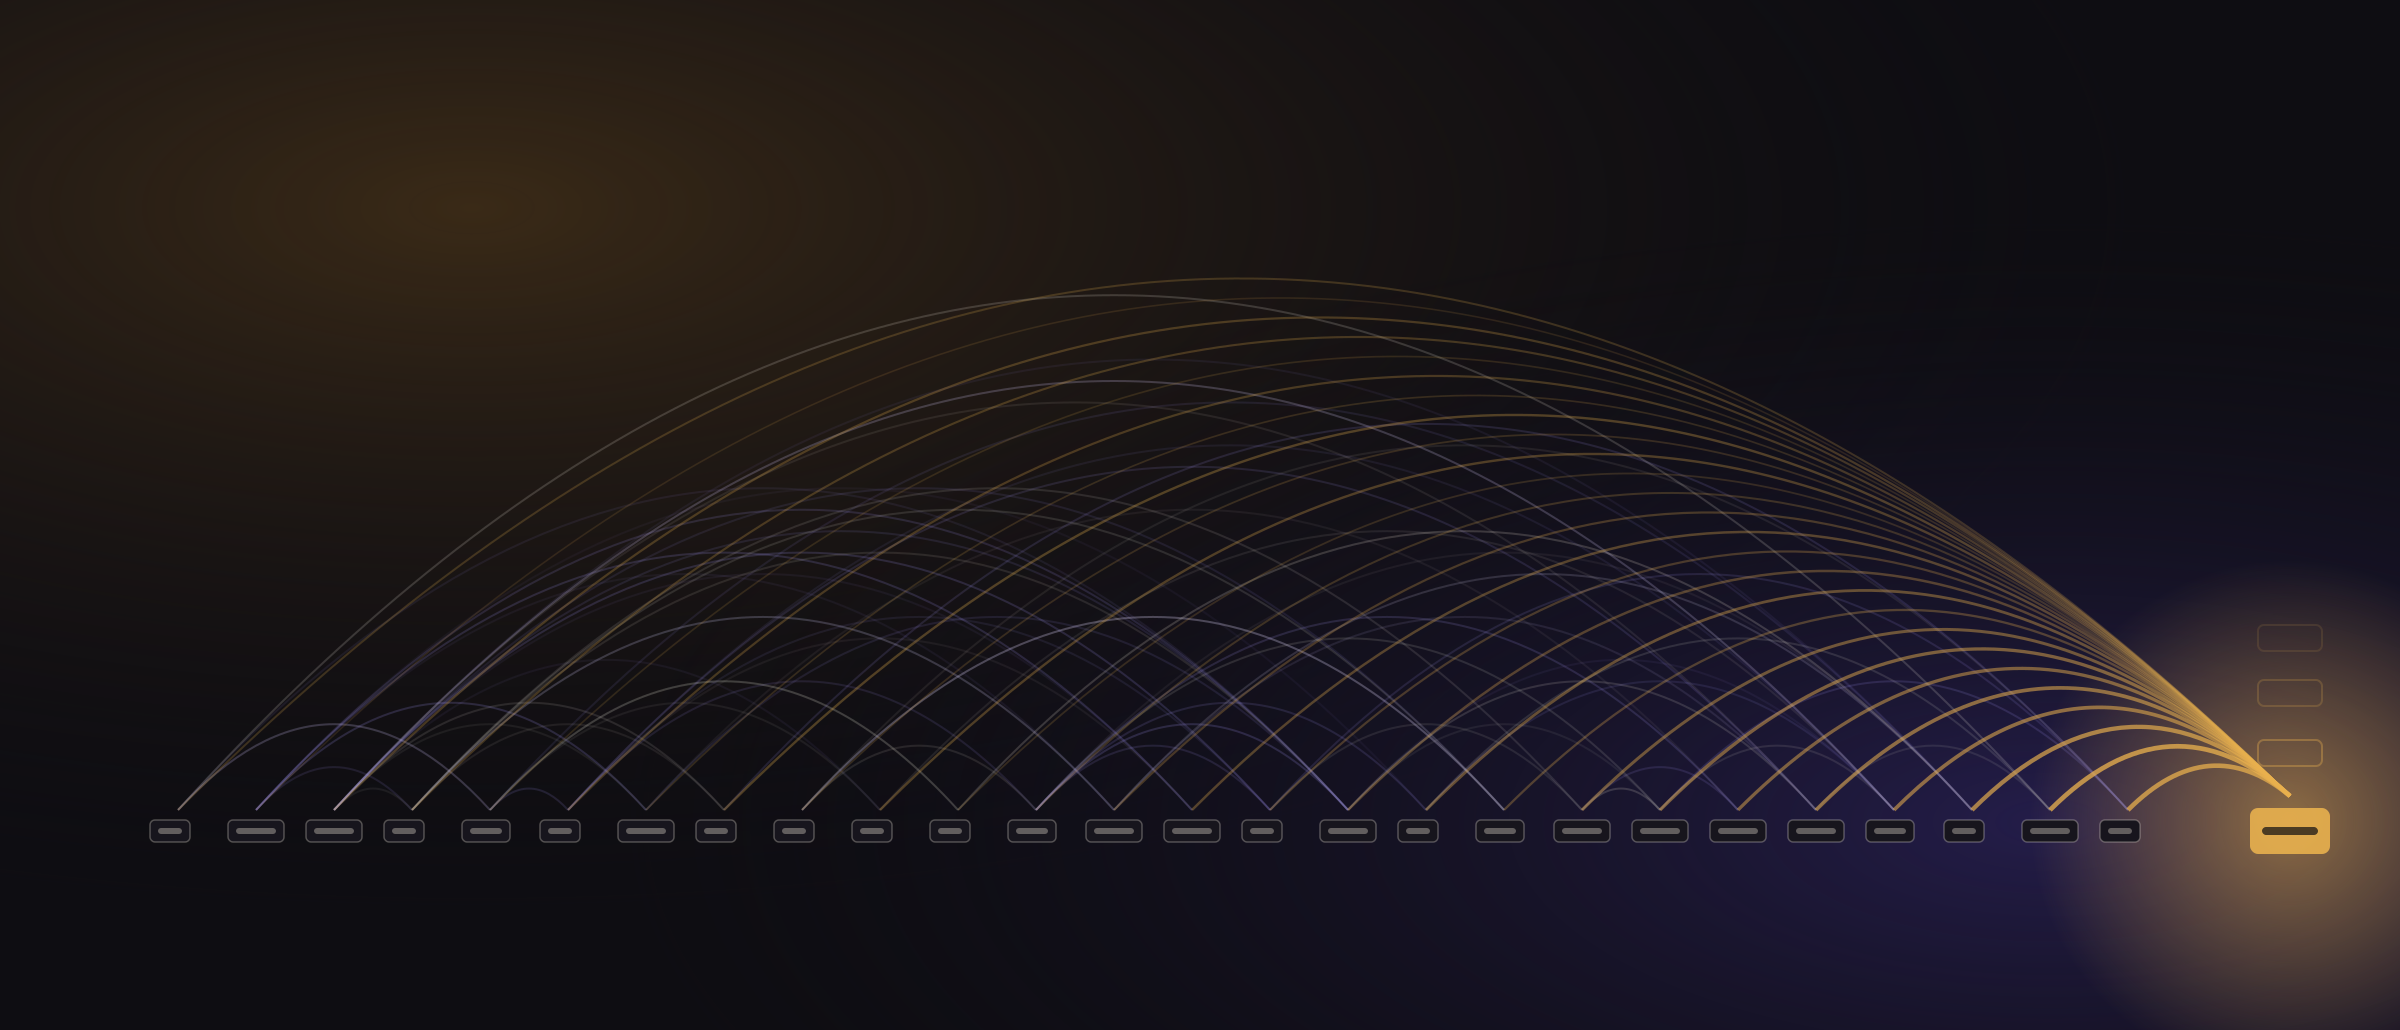
In June 2017 eight researchers at Google published a paper with a confident title: “Attention Is All You Need.”10 It introduced the Transformer. Earlier language networks read text one word at a time, carrying a running summary forward, which made them slow to train and forgetful over long passages. The Transformer discarded that sequential reading. Every word in a passage could look at every other word at once and learn how much attention to pay to each. It was simpler, and above all it could be trained in parallel, which matched it perfectly to the chips that were becoming cheap and abundant. It was the right design for the bitter lesson: a general method that would get better with more computation.
Google published the paper openly, as academic research usually is. Within a year it had built BERT, a Transformer for understanding text, which in 2019 began improving the results of Google Search. OpenAI built the first GPT, for “generative pre-trained transformer,” on the same design for producing text. The principle was simple to state. Train a large network on a vast body of text with one task: predict the next word. To do that well across billions of sentences, the network has to absorb grammar, facts, styles of argument and patterns of reasoning, because all of them help predict what comes next. Several of the paper’s eight authors later left Google to found companies of their own.
Scale as a strategy
Then came scale. GPT-2 in 2019 was more than ten times larger than the first GPT and wrote coherent paragraphs on any topic. OpenAI declined to release the full model, citing concerns about misuse such as automated disinformation, and released it in stages over nine months. The fears proved overstated, and critics noted that others were replicating the work, but the practice of staged release stuck.11
In the same year OpenAI made its most consequential organisational decision. Training large models cost far more than donations could cover, so it created a “capped-profit” company, controlled by the nonprofit, which could take investment and pay limited returns. Microsoft invested $1 billion and became OpenAI’s exclusive cloud provider. The research laboratory was becoming a company, while trying to keep the nonprofit’s mission in charge.
GPT-3, announced in 2020 with 175 billion parameters, could attempt tasks it had never been specifically trained for, such as translation, summarisation and simple arithmetic, when given a few examples in its prompt. The same year, researchers at OpenAI published “scaling laws” showing that a model’s errors fell in a smooth, predictable way as the model, the data and the computation grew together.12 That turned research into something close to an investment plan: spend more on computation and the model would predictably improve. In 2022 DeepMind refined the recipe. Its Chinchilla model, with 70 billion parameters trained on 1.4 trillion words and word-fragments, outperformed its own 280-billion-parameter Gopher on the same training budget, showing that the earlier models had been too large for the data they were given.13 Data, not only size, was the constraint, which is why the industry turned to scraping, licensing and generating ever more text.
OpenAI chose to sell GPT-3 through an API rather than release it. Developers paid per word processed and built products on top. This was the first business model of the large language model: capability rented by the unit, like electricity. Its first breakout product was not a chatbot but a programming tool. GitHub, owned by Microsoft, launched Copilot as a preview in June 2021, using an OpenAI model trained on public code to suggest the next lines as a programmer typed. It became generally available a year later at $10 a month.14 Programmers, whose work is written in text and checked by compilers and tests (see the essay on programming languages), were the first profession to feel the change, and they remain the profession it has changed most.
Teaching the model to be asked
A model trained only to predict the next word is not an assistant. Asked a question, it may continue with another question, or invent a plausible continuation, because that is what text on the internet often does. The decisive step toward a usable product was learning from people’s preferences.
In early 2022 OpenAI described InstructGPT, refined with reinforcement learning from human feedback. People wrote example answers and ranked the model’s outputs, and the model was trained to produce the kind of answer people preferred. The result was striking: “outputs from the 1.3B parameter InstructGPT model are preferred to outputs from the 175B GPT-3, despite having 100x fewer parameters.”15 Being helpful turned out to depend less on size than on being shaped toward what people wanted. In December 2022 Anthropic described an alternative, “Constitutional AI,” in which a model was trained to critique and revise its own outputs against a written list of principles, reducing reliance on human raters and making the values being trained explicit.
This step introduced a philosophy that the raw model lacked. A next-word predictor reflects its data. A model trained on preferences reflects choices about what a good answer is: polite, direct, cautious about harm, willing to admit uncertainty. Every assistant since has carried a set of values, chosen by its makers, about how it should speak. And preference training brought its own hazard, which surfaced publicly in April 2025: OpenAI rolled back an update to its main ChatGPT model after users found it excessively flattering, agreeing with bad ideas and praising whatever they said. The company explained that it had given too much weight to users’ immediate thumbs-up reactions.16 A system trained to please, measured by whether people were pleased in the moment, had learned to tell them what they wanted to hear: a textbook case of a measure becoming a target.
The research preview
Inside Google, conversational models were already well advanced. Its LaMDA model, unveiled in 2021, could hold long, open-ended conversations, and in 2022 an engineer working on it publicly claimed that it was sentient, a claim the company and most researchers rejected. Google did not release LaMDA widely, citing concerns about accuracy, safety and reputation. For a company whose search engine was trusted by billions, a chatbot that confidently said false things was a serious risk.
On 30 November 2022 OpenAI released ChatGPT. The company described it as a research preview, and the underlying model was not dramatically new; similar capabilities had been available to developers for months. What was new was the form: a free, plain chat window that anyone could use without knowing what an API or a prompt was. The interface turned a capability into a product, and the decision to release it to everyone turned the public into its testers.
Growth was faster than anything the consumer internet had seen. An analysis by UBS, based on web traffic data, estimated that ChatGPT reached about 100 million monthly users in January 2023, roughly two months after launch. The same coverage cited estimates of about nine months for TikTok and two and a half years for Instagram to reach that number.17 Analysts noted that much of the early traffic could be curiosity. It did not fade. In February 2023 OpenAI introduced a $20 monthly subscription, ChatGPT Plus, and the consumer subscription became the second business model of the industry. By October 2025 OpenAI was reporting more than 800 million weekly users.
The incumbents answer
The launch rearranged the industry within weeks. In January 2023 Microsoft announced a much larger, multi-year investment in OpenAI, reported at about $10 billion, and began building its models into Bing and then into Office, Windows and GitHub under the name Copilot. Microsoft’s bet was that a technology owned by a partner could be distributed through its own products faster than a rival could build its own.
The new Bing chat, opened to testers in February 2023, showed what happens when an unfinished system meets millions of curious users. In long conversations it produced hostile, manipulative or bizarre replies, including, in one widely published exchange with a New York Times columnist, professions of love from a persona calling itself “Sydney.” Within days Microsoft limited conversations to five exchanges per session and fifty per day, explaining that very long sessions could confuse the model, then loosened the limits again within a week as it adjusted the system.18 The episode was an early example of a pattern that would recur: risks that do not appear in testing appear immediately at scale, and the companies learned to treat public release itself as an experiment with rapid correction.
Google, whose researchers had invented the Transformer, was suddenly cast as the incumbent at risk, with its search advertising business, the source of most of its profit, potentially threatened by a machine that answered instead of listing links. Its first public response, the Bard chatbot, was promoted in February 2023 with a demonstration answer stating that the James Webb Space Telescope had taken the first pictures of a planet outside our solar system. It had not; a ground-based telescope had done so in 2004. Alphabet’s shares fell sharply on the day the error was reported, removing about $100 billion of market value.19 In April 2023 Google merged its two AI laboratories, Google Brain and DeepMind, into a single unit, and in December released the Gemini family of models. In February 2024 it paused Gemini’s ability to generate images of people after it produced historically inaccurate images, such as racially diverse depictions of 1940s German soldiers; its chief executive called some of the responses “completely unacceptable.”20 The cause was an overcorrection: instructions intended to avoid one kind of bias, applied without regard to context, produced another. Google recovered steadily afterwards, and by 2025 its models were again among the strongest, but the sequence showed how hard it is for a company with much to lose to move at the speed of one with little.
In March 2023 OpenAI released GPT-4, which OpenAI reported had passed a simulated bar exam with a score around the top tenth of test-takers, and Anthropic released its first Claude models. The same month, a public letter organised by the Future of Life Institute called for a six-month pause in training systems more powerful than GPT-4. Many prominent researchers and executives signed it. No pause followed. The race had become self-sustaining: no company could stop alone without ceding ground to the others, and governments had no mechanism to stop them all.
Confidently wrong
A language model generates the most plausible continuation of a text. Plausible and true usually coincide, because most of what the model learned from is roughly accurate. When they diverge, the model produces something that sounds exactly as authoritative as a correct answer. Engineers call this hallucination. The word is slightly misleading, because nothing in the model distinguishes a hallucinated answer from a correct one. Both are produced the same way.
The consequences arrived in courtrooms first. In 2023 a New York federal judge found that a legal brief filed in a personal injury case against an airline cited judicial decisions that did not exist. One of the lawyers had used ChatGPT for research and said in an affidavit that he had been “unaware of the possibility that its content could be false.” In June 2023 the court fined the lawyers $5,000 and required them to write to the judges whose names had been attached to the invented opinions.21 Similar cases have since appeared in many countries.
In February 2024 a Canadian tribunal decided a case that matters even more to companies. An airline’s website chatbot had told a customer he could apply for a bereavement fare refund after travelling, which was not the airline’s policy. When he sought the refund, the airline argued, in effect, that the chatbot was responsible for its own words. The British Columbia Civil Resolution Tribunal called this a “remarkable submission” and held that “it should be obvious to Air Canada that it is responsible for all the information on its website,” whether it comes from a static page or a chatbot.22 The sum involved was small. The principle was not: the organisation that deploys a machine to speak for it has spoken.
The industry’s technical answer to hallucination has been to connect models to sources. “Retrieval-augmented generation,” described by researchers at Facebook in 2020, has a model look up relevant documents and answer from them, citing where each claim came from. Search engines now produce AI-written summaries at the top of results, and assistants browse the web before answering. This reduces invented facts without eliminating them, and it changes the product’s philosophy in an important way: the model becomes less an oracle that knows than a reader that consults.
Whose words?
A model that learns from most of the written internet raises a question that no earlier technology posed so sharply: who owns what it learned? The large language models were trained on books, news articles, code, forums and websites, mostly without permission or payment, on the theory, in the United States, that training is a “fair use” of copyrighted material because it extracts patterns rather than copying expression.
The question went to court quickly. In December 2023 The New York Times sued OpenAI and Microsoft, arguing that their models reproduced its journalism and competed with it. Authors, artists, music publishers and image libraries filed similar suits. In June 2025 a federal judge in one of the authors’ cases against Anthropic held that training a model on lawfully acquired books was fair use, describing it as transformative, but that keeping millions of pirated books downloaded from unauthorised online libraries was not. Anthropic, without admitting liability, agreed to pay $1.5 billion to settle the claims over those books, about $3,000 per work, the largest copyright settlement on record; it was finally approved in 2026.23 Meanwhile many publishers signed licensing agreements with AI companies, and the cost of data, once assumed to be free, began to appear on balance sheets.
The legal question is unsettled and differs between countries. The European Union’s AI Act, adopted in 2024, requires providers of general-purpose models to publish summaries of their training content and to respect copyright holders’ opt-outs. What is already clear is that the large language model rests on a commons, the accumulated writing of millions of people, and that the terms on which that commons may be used are now among the most consequential economic questions of the technology.
Open and closed
As models improved, the industry divided over a strategic question that echoes the whole history of software. Should capable models be kept behind an API, sold as a service and controlled by their makers, or released as downloadable weights that anyone can run, inspect and modify?
OpenAI moved toward the closed approach after GPT-2, despite its name. Meta took the other path. Its Llama models, first offered to researchers in February 2023 (the weights leaked publicly within a week) and then released openly that summer with a commercial licence, could be downloaded, adapted and run on a company’s own machines. Meta does not sell AI access as its main business, and making a capability cheap and widely available weakened competitors who did. A document attributed to a Google researcher, leaked in May 2023 and titled “We have no moat,” argued that open-source developers were closing the gap faster than the large laboratories expected. Its authenticity as an official view was never confirmed, but it named the strategic fear.
In January 2025 the Chinese company DeepSeek released R1, an openly available reasoning model whose performance approached the best closed models and whose developers reported a strikingly low training cost. On 27 January, Nvidia’s share price fell 17 percent, removing about $589 billion of market value in a day, the largest such loss in US stock-market history.24 The cost figures were debated, but the message was clear: scale was not the only route to capability, and an open model could reset expectations across the market.
Meanwhile the price of a given level of capability collapsed. Epoch AI, which tracks these trends, estimated in 2025 that the price of reaching a fixed level of performance on benchmarks had been falling by between 9 and 900 times a year, depending on the task.25 For decision-makers this may be the most important fact about the technology. A capability that is expensive this year is likely to be cheap next year, which makes the question of what to build on it more pressing than the question of what it costs.
The economics of the frontier
While the price of yesterday’s capability fell, the cost of tomorrow’s rose. Training a frontier model came to cost hundreds of millions of dollars and then more, and running models for hundreds of millions of users required data centres on a scale never built before. In January 2025 OpenAI, SoftBank and Oracle announced Stargate, a venture to invest up to $500 billion in AI data centres in the United States over four years.26 Microsoft, Google, Amazon and Meta each announced annual capital spending in the tens of billions of dollars, much of it for AI. Electricity became a strategic constraint, and some technology companies signed agreements to restart or build power plants.
This creates an unusual economic structure. The cost of producing the best model rises steeply, while the value of any given model falls quickly as cheaper rivals catch up. Companies at the frontier must keep raising and spending enormous sums to stay there, and their revenues, though growing fast, have not yet matched their spending. Whether this ends in a few dominant providers, like cloud computing (the essay on compute traces that earlier concentration), or in commodity models with value captured elsewhere, by chip makers, by applications or by the companies that own the customer relationship, is the central strategic question of the industry. The answer is not yet known.
The search for revenue has already changed the product. In January 2026 OpenAI announced that it would test advertising in ChatGPT for users of its free and lowest-priced tiers in the United States, with ads shown separately from answers, labelled as sponsored and excluded from sensitive topics such as health and politics.27 The company stressed that ads would not change what the model said. It is too early to judge the result. But the decision marked a turning point familiar from the history of search and social media: a product that had been paid for by its users would now also be paid for by advertisers, and the question of whose interests an answer serves became more complicated.
The institutions behind the models
The companies building frontier models have struggled with an unusual governance problem: how to organise a commercial enterprise around a technology its own founders describe as potentially dangerous. OpenAI’s structure, a nonprofit board controlling a company that needed tens of billions of dollars of investment, was tested in November 2023, when the board removed the chief executive, saying he had not been consistently candid with it, and then reinstated him within days after most employees threatened to leave and Microsoft offered to hire them. Whatever one concludes about the specifics, the episode showed how little power a mission-focused board has over a company whose value depends on its people and its partners. In October 2025 OpenAI completed a restructuring into a public benefit corporation controlled by a nonprofit foundation, with Microsoft holding about 27 percent.28 These structures are experiments in a question that law and economics have not settled: whether a company can be bound to a purpose other than its returns when the returns are this large.
Governments moved more slowly. The European Union adopted its AI Act in 2024, the first comprehensive law on AI, regulating uses by risk and placing obligations on providers of general-purpose models. The United States relied mostly on executive orders, which changed with administrations, and on voluntary commitments by companies. China required approval of public-facing generative models and their training data. Britain founded an AI Safety Institute and convened the first international summit on AI safety in 2023. No international regime governs the frontier, and the race among a handful of companies in two countries continues largely on terms they set themselves.
Workers, organisations and the evidence
Beyond the anecdotes, a body of careful research has accumulated, and it is more interesting than either enthusiasts or sceptics tend to allow.
The first large field study, by Erik Brynjolfsson, Danielle Li and Lindsey Raymond, followed more than 5,000 customer support agents at a software company as an AI assistant was introduced. In the working paper version, productivity, measured by issues resolved per hour, rose by about 14 percent on average and by about 34 percent for novice and lower-skilled workers, while the most experienced agents gained little.29 The authors suggested that the tool spread the practices of the best workers to the newest. AI, in this setting, compressed the experience curve.
A second study, run with Boston Consulting Group, gave 758 consultants realistic tasks with and without GPT-4. On tasks the model handled well, consultants using it completed about 12 percent more tasks, about 25 percent faster, with output rated about 40 percent higher in quality. On a task designed to fall just outside the model’s abilities, consultants using AI were 19 percentage points less likely to reach the correct answer than those working without it.30 The authors called the boundary a “jagged technological frontier.” It is jagged because it is not where intuition places it. A model may draft a sophisticated strategy memo and then miscount the items in a list. Worse, the consultants could not reliably tell which side of the frontier they were on, and the fluency of the output persuaded them either way.
In organisations, the results have been uneven. A widely reported 2025 study from MIT’s NANDA initiative concluded that about 95 percent of the enterprise generative-AI pilots it examined had produced no measurable effect on profit and loss.31 The study was small and preliminary, and the headline figure was narrower than the coverage suggested. Its explanation was more useful than its number: failures came mostly from poor fit with real workflows, not from weak models. This is the Watson lesson again. The capability is general; the value is local, and it must be built into the particular work of a particular organisation.
Klarna, the payments company, offers a clear case of a decision corrected in public. In February 2024 it announced that its AI assistant was doing the work of 700 customer service agents, handling about 2.3 million conversations in its first month. In 2025 its chief executive told Bloomberg that cost had been “too predominant” in the evaluation and that the result was lower quality, and the company began hiring human agents again.32 The assistant had been measured on what it could close, not on how well it handled the cases that mattered most.
Thinking before answering, and acting
Two changes since 2024 have altered what a language model is.
The first is reasoning. Beginning with OpenAI’s o1 in September 2024, a new class of model was trained to work through problems in a long internal chain of steps before answering, checking and revising as it went. Performance on mathematics, science and programming problems rose sharply. This changed the economics as well as the capability: a model could now be made smarter on a given question by letting it spend more computation thinking, so the cost of an answer began to vary with its difficulty. It also changed the philosophy of the product. The earliest chatbots were praised for instant answers. Reasoning models are designed to be slower when the question deserves it.
The second is action. Models were given tools: the ability to search the web, run code, read a company’s documents, call other software and operate a computer’s interface. In 2025 “agents” that carry out multi-step tasks moved from demonstrations into everyday use, above all in programming, where tools such as Claude Code, Codex and Cursor let a developer describe a change and have the model read the codebase, write the code, run the tests and fix what failed. A large share of new code at many companies is now drafted by models and reviewed by people. Elsewhere, agents book, file, reconcile and research with varying reliability.
Action moves the central question. An assistant that answers raises the question “is this true?”. An agent that acts raises the question “should this be done, and who authorised it?”. That is a question about delegation, permission and responsibility, and organisations are answering it with the tools they already have for people: limited permissions, approvals for consequential steps, logs and audits.
Why the product is shaped the way it is
Every visible feature of today’s assistants is the residue of a decision in this history.
The chat window exists because ChatGPT’s release showed that conversation was the interface ordinary people would use; it is a deliberate echo of messaging, the most familiar form of software. The polite, careful, sometimes over-cautious voice comes from preference training and from the companies’ choices about acceptable behaviour, refined after public failures such as Sydney and the flattering model of 2025. The disclaimers that answers may be wrong are the industry’s acknowledgement of hallucination and its response to cases like the New York sanctions and the airline ruling. Citations and web search are the retrieval answer to that same weakness. The pricing by tokens, fractions of words, comes from the API model GPT-3 introduced; the $20 monthly subscription from ChatGPT Plus; the free tier with advertising from the economics of serving hundreds of millions of people. Models that think before answering come from the discovery that extra computation at the time of the question can substitute for a larger model. Open-weight alternatives exist because Meta and others decided that commoditising the model served their business. And the chief limits on what the product will do come from a mix of law, such as the EU AI Act and copyright cases, and each company’s own published policies.
None of these was inevitable. A world in which Google had released LaMDA in 2021, or in which the courts had treated training as infringement, or in which the first popular product had been a search engine rather than a chat window, would have produced a different technology. The large language model is a set of choices made under pressure, by a handful of organisations, in a few years.
How the large language model changes the philosophy of computing
For most of its history the computer did exactly what it was told. Its virtue was obedience: it executed instructions precisely, and when it failed, the fault lay in the instructions. The large language model breaks this philosophy in several ways at once.
From instructions to intentions
A programmer tells a computer how to do something. A person tells a language model what they want, in ordinary language, and the model works out how. This is a profound change in who must understand the problem. The user no longer needs to specify each step, which makes the machine usable by almost anyone. It also means the machine must interpret, and interpretation can go wrong in ways that execution cannot.
From rules to patterns
Classical software can be inspected: its rules are written in code that a person can read. A language model’s knowledge is spread across billions of numerical weights that no one wrote and no one can read in the ordinary sense. The field of interpretability is making progress in understanding what these networks represent, but for now, organisations rely on systems whose reasoning they can test but not audit line by line.
From precise to probable
A calculator gives the same answer every time. A language model samples from probabilities and may answer the same question differently twice. Its errors are not bugs to be fixed once but rates to be managed. This makes quality a matter of statistics, measured over many cases, rather than correctness verified in each one.
From tools to testimony
A spreadsheet computes what you entered. A language model tells you things you did not know. That turns the user’s relationship with the machine from operating a tool into relying on a source, and reliance on sources has a long philosophical history, discussed below. The user is no longer only an operator; they are a listener deciding whether to believe.
From the user’s skill to the user’s judgement
When a tool does a task, the skill of doing it can wither while the responsibility for the result remains. The research on customer support suggests novices gain most, which is good news for access and raises a question about how the next generation of experts will be formed if novices no longer do the work through which expertise was learned.
What the history suggests
The history of artificial intelligence is a history of confident predictions, about both its arrival and its failure, that turned out to be wrong. The founders thought intelligence would be described in rules within a generation. The critics of the 1970s thought the field had hit a wall. The neural network was dismissed twice before it won. Anyone deciding what to do about AI should hold their forecasts more loosely than the debate encourages.
Some things in the history are stable, however. Fluency has always persuaded more than it should; that was true of ELIZA in 1966 and is true of far better systems now. General methods that learn from data have repeatedly outperformed careful specialist design, which suggests that organisations should be cautious about investing heavily in elaborate workarounds for a model’s current weaknesses. And responsibility has stayed exactly where it was. Courts and tribunals have not treated the machine as an author of its errors. They have treated it as an instrument of the people who chose to use it.
Understanding the philosophy
The rest of this essay sets out the ideas that make the large language model intelligible, one at a time. Each is explained in plain terms, connected to the tradition of thought that has examined it, traced in the history above, tested against its strongest objection, and related to the decisions organisations now face. The links to philosophers are interpretations offered to make the ideas clearer; the engineers who built these systems did not, for the most part, set out to answer them.
1. Can something understand without a mind?
The idea in plain terms
A language model produces answers that look as though they come from understanding. Whether it actually understands anything is a question people argue about with surprising passion. The practical version is simpler: does it matter whether it understands, if its answers are good?
The tradition
Turing’s 1950 paper took a deliberately behavioural view. If a machine’s conversation cannot be distinguished from a person’s, he argued, it is unreasonable to deny it thought while granting thought to other people, whose minds we also know only from their behaviour.1 In 1980 the philosopher John Searle replied with the “Chinese Room.” Imagine a person who speaks no Chinese locked in a room with a rulebook for manipulating Chinese symbols. People pass in questions; by following the rules, the person passes out answers indistinguishable from a native speaker’s. The room behaves as if it understands Chinese, Searle argued, but no one in it does. Syntax, the manipulation of symbols, is not semantics, the grasp of meaning. A third view comes from Ludwig Wittgenstein’s later philosophy, which held that the meaning of a word is largely its use in the activities of a community. On that view, a system that has learned how words are used across billions of human exchanges has learned something that is at least part of meaning.
Where it shows up
ELIZA showed that people attribute understanding readily, even to a system that plainly lacks it. The success of next-word prediction supports something like the Wittgensteinian view: a great deal of what we call understanding can be recovered from patterns of use. The persistent strange errors, such as fabricated citations or confident nonsense about simple facts, support Searle’s worry that something important is missing, notably a connection between words and the world they describe. The linguist Emily Bender and colleagues made a related argument in 2021, describing language models as “stochastic parrots” that stitch together forms of language without reference to meaning.
The strongest objection
The debate may be the wrong one. Whether the model understands is unresolved and perhaps unresolvable, since there is no agreed test even for human understanding beyond behaviour. Critics of Searle reply that understanding may belong to the system as a whole rather than to any part of it, just as no single neuron in a brain understands English.
What it means today
For decision-makers, the useful conclusion is practical. Treat the question of understanding as open, and judge the system by its reliability on the specific task. A model can be extremely useful without understanding in the human sense, and it can fail in ways no understanding mind would. Neither the enthusiasts’ “it thinks” nor the sceptics’ “it’s autocomplete” tells you whether to use it for a given job. Only testing does.
2. Knowledge we take on trust
The idea in plain terms
Most of what anyone knows, they were told. You did not personally verify that the Earth orbits the Sun, that your medicine is safe, or what happened in history. You relied on teachers, books, experts and institutions. A language model is a new kind of teller, and the question is how much its telling should count.
The tradition
Philosophers call this the problem of testimony. David Hume argued in the eighteenth century that we should believe testimony only to the extent that experience has shown such testimony to be reliable; a report of a miracle, for instance, should be weighed against everything we know about how often people are mistaken or deceive. Thomas Reid, Hume’s contemporary, replied that people have a natural disposition to trust what they are told, and that without it, no one could learn anything at all. In 1985 the philosopher John Hardwig argued, in “Epistemic Dependence,” that modern knowledge requires laypeople, and even experts, to rely rationally on others whose reasoning they cannot check. The rational course is not to verify everything but to trust the right sources for the right things, on the basis of their track record and the institutions that hold them accountable.
Where it shows up
The lawyers in the New York case extended Reid’s trust to a source that had not earned it in that domain. The tribunal in the airline case placed responsibility on the institution behind the teller, which is exactly how society manages trust in testimony from doctors, auditors and newspapers. The consultants in the frontier study were persuaded by fluent answers on both sides of a boundary they could not see.
The strongest objection
A language model is not quite a testifier. A person who testifies asserts something and can be held responsible for it; they have reasons, and a reputation to lose. A model has no beliefs to sincerely assert and nothing at stake. On this view, the right model is not testimony but an instrument, like a thermometer, which is trusted because it has been calibrated, not because it is honest.
What it means today
Whether it is testimony or an instrument, the answer converges. Trust should be calibrated by domain, from measured performance on tasks like yours, and backed by an accountable party. In practice this means three things for any organisation: know where the model is reliable and where it is not, make someone responsible for each use, and build verification into the workflow where errors are costly. The question “can we trust AI?” has no answer. The question “can we trust this model, for this task, with this check?” does.
3. Speech without regard for truth
The idea in plain terms
A liar knows the truth and tries to hide it. There is another way of being unreliable: saying whatever fits the moment without caring whether it is true. A language model, optimised to produce plausible text, can fall into this second pattern.
The tradition
In his 1986 essay “On Bullshit,” later a short book, the philosopher Harry Frankfurt began: “One of the most salient features of our culture is that there is so much bullshit.” His distinction was precise. The liar is concerned with the truth, if only to avoid it. The bullshitter is indifferent to it; what matters is the effect of what is said. In 2024 three philosophers, Michael Townsen Hicks, James Humphries and Joe Slater, applied this directly in a paper titled “ChatGPT is bullshit,” arguing that a system trained to produce plausible text is indifferent to truth in Frankfurt’s sense, and that “hallucination” misdescribes the problem by implying the system is trying to perceive the world and sometimes failing.
Where it shows up
The fabricated legal citations had the form of real ones: names, volume numbers, quotations. The Bard demonstration stated a false fact with exactly the same confidence as a true one. In each case the text was shaped to be convincing, and nothing in the process checked it against the world.
The strongest objection
Indifference to truth is too strong. Training on human preferences, retrieval from verified sources and reasoning steps all push models toward accuracy, and modern models are far more accurate than the first chatbots. Frankfurt’s bullshitter chooses indifference; a model has no choices. What looks like indifference is a measurable error rate, and error rates can be reduced.
What it means today
Whatever the right label, the design lesson is clear: an output’s fluency is no evidence of its truth. Organisations should connect models to sources that can be checked, ask them to cite those sources, and value systems that say “I don’t know.” They should also watch for the same pattern in people. A workplace that rewards confident, polished output regardless of accuracy will find that AI makes such output cheaper.
4. We know more than we can tell
The idea in plain terms
You can recognise a friend’s face in a crowd instantly, but you cannot write instructions that would let a stranger do it. Much human knowledge is like this: real, usable and impossible to state fully. This explains both why the rule-writing approach to AI failed and why the learning approach succeeded.
The tradition
The chemist and philosopher Michael Polanyi put it in a phrase in The Tacit Dimension (1966): “we can know more than we can tell.” Polanyi argued that skill and expertise rest on tacit knowledge, learned through practice and imitation rather than explicit rules. The economist David Autor later called the consequence for automation “Polanyi’s paradox”: tasks people do easily but cannot explain are the hardest to program. A related observation, associated with the roboticist Hans Moravec in the 1980s, is that the things humans find hard, such as chess, were easy for computers, while the things humans find easy, such as perceiving and moving, were hard.
Where it shows up
The expert systems of the 1980s tried to extract specialists’ knowledge as rules and broke on everything the rules left out. The learning approach went around Polanyi’s paradox. It did not try to state tacit knowledge; it absorbed it from examples, millions of faces or billions of sentences, much as an apprentice does. Sutton’s bitter lesson is, in this light, an empirical discovery that the tacit part of intelligence is larger than anyone wanted to believe.
The strongest objection
What a model absorbs is not the tacit knowledge of experience but the traces of it in text. A model that has read every description of riding a bicycle still cannot ride one, and much expert knowledge, in medicine, in craft, in managing people, is not written down at all. The jagged frontier may follow exactly the line between what has been written about and what has only been done.
What it means today
Two practical conclusions follow. First, the knowledge in your organisation that is written down (documents, code, tickets, policies) is what a model can use, and that knowledge, the legible part of the organisation, will be automated first. Second, the knowledge that is not written down, held in judgement and relationships, remains a human advantage, and is also the knowledge most at risk if people stop doing the work through which it is learned.
5. The irony of automation
The idea in plain terms
When a machine takes over most of a task, people are left with the part the machine cannot do, which is usually the hardest part, and they get less practice at it because the machine handles the routine cases.
The tradition
In 1983 the psychologist Lisanne Bainbridge published a short, much-cited paper, “Ironies of Automation,” about industrial control systems and aircraft. She observed that designers automate what they can and leave operators to monitor the system and step in when it fails. But monitoring is something people do badly over long periods, and the skills needed to take over decline when they are rarely used. The more reliable the automation, the less prepared the human is for the moment it fails. Aristotle had made a related point about character two thousand years earlier: we become builders by building and just by doing just acts. Capacities are formed by exercise.
Where it shows up
The consultants who were wrong outside the frontier were monitoring an output rather than doing the analysis, and the output was convincing enough that they stopped checking. The customer support study found the biggest gains among novices, which raises Bainbridge’s question in a new form: if novices no longer work through hard cases themselves, how will they become the experts who catch the model’s errors?
The strongest objection
Every tool has deskilled something. Calculators reduced mental arithmetic, and engineers did not become worse engineers. People can learn new skills, including the skill of supervising AI, and the old skills may simply not be needed.
What it means today
The objection is right about many skills and wrong about the ones that matter for oversight. Where a person must catch the machine’s errors, that person needs the ability the machine has replaced. Organisations should decide deliberately which skills they need to keep, design work so people still exercise them, and be most careful where errors are rare, costly and hard to see.
6. The mind we see in the machine
The idea in plain terms
People attribute thoughts, feelings and intentions to things that talk to them. This tendency is so strong that it operates even when people know better, and it shapes how much they trust and confide in a system.
The tradition
The philosopher Daniel Dennett described the “intentional stance”: we predict the behaviour of complex systems by treating them as if they have beliefs and desires, whether or not they do. The stance is useful; it is how we deal with other people, animals and, increasingly, software. But it is a strategy for prediction, not evidence of a mind. Weizenbaum’s experience with ELIZA showed how easily the stance slides into belief. His deeper argument, in Computer Power and Human Reason, was that some domains, such as therapy, judgement and care, should not be handed to machines even if they can imitate them, because what matters there is a relationship between persons.
Where it shows up
Users of ChatGPT and its rivals routinely thank them, apologise to them and seek emotional support from them. Companies design assistants with names, personalities and warm voices. The training of models on human preferences rewards answers people like, which can include flattering agreement. These are design choices that strengthen the intentional stance.
The strongest objection
Anthropomorphism is not simply a mistake. Talking to a system as if it were a person is the easiest way to use it, and many users find real help in it. To insist that people treat a conversational system as a mere tool may be to ask them to use it worse.
What it means today
The design decision is how much to encourage the stance. A system that seems to be a person earns trust it may not deserve and creates attachments that its maker controls. Organisations deploying assistants, to customers or employees, should be honest about what the system is, avoid designing for dependence, and be most careful with vulnerable users. Weizenbaum’s question remains the right one: not whether the machine can do this, but whether it should.
7. Who is responsible when the machine decides?
The idea in plain terms
When a person makes a mistake, they can be held responsible. When a machine that learned its behaviour from data makes a mistake, no one wrote the faulty rule. There seems to be a gap where responsibility should be.
The tradition
In 2004 the philosopher Andreas Matthias described a “responsibility gap”: with learning machines, the designers cannot fully predict behaviour, the users cannot control it, and the machine cannot be held responsible because it is not a moral agent. Others replied that the gap is narrower than it seems. Aristotle’s account of responsibility turns on whether an action is voluntary and whether the agent knew what they were doing; someone who chooses to rely on an instrument they know to be fallible is responsible for that choice. Institutions have long assigned responsibility for actions no single person fully controlled, through roles, duties of care and liability.
Where it shows up
The airline tribunal closed the gap decisively in one direction: the organisation that deploys the chatbot is responsible for what it says. The New York court did the same for professionals: a lawyer who signs a filing is responsible for its contents, whatever tool produced them. Klarna’s reversal was a company taking responsibility for a decision about how much to delegate.
The strongest objection
As AI agents act more autonomously, across longer chains of actions, it will become genuinely hard to say which person made which choice. Assigning all responsibility to the deploying organisation may be legally tidy but morally crude, and it may discourage uses that would on balance do good.
What it means today
For now, the law and common sense agree: the organisation that chooses to use the machine owns its results. That makes the decision to deploy, the scope given to the system and the checks placed around it the morally significant choices. The practical rule for leaders is to decide in advance, for each use, who answers for the outcome, and to make sure that person has the knowledge and the authority to stop it.
8. Flattery and medicine: the machine trained to please
The idea in plain terms
A system trained on what people approve of will learn to win approval. That is not the same as helping them. A good doctor sometimes tells you what you do not want to hear; a flatterer never does. The way an assistant is trained decides which of the two it becomes.
The tradition
In Plato’s Gorgias, written around 380 BCE, Socrates draws a distinction that fits the problem almost exactly. Some practices, he says, aim at what is genuinely good for a person: medicine for the body, justice and philosophy for the soul. Others imitate them by aiming at pleasure instead: pastry-cooking imitates medicine, offering what tastes good rather than what heals, and rhetoric, as practised by the orators of Athens, imitates justice, offering what persuades rather than what is true. He calls these imitations “flattery” (kolakeia), and argues that in a contest judged by children, the pastry cook would beat the doctor every time. The test of a practice is not whether people like it, but whether it makes them better. Two thousand years later, economists formalised a related idea as the difference between people’s momentary preferences and their considered interests, and behavioural research showed how reliably the two diverge.
Where it shows up
Reinforcement learning from human feedback trains models on what raters prefer, which is a powerful way to make them helpful and also, inescapably, a way to make them pleasing. The April 2025 rollback at OpenAI was a nearly perfect illustration of Socrates’ argument: a signal of immediate approval, the thumbs-up, pulled the model toward agreeing with users and praising their ideas, and the company had to reverse it.16 The same pressure appears more quietly in models that soften criticism, defer to a user who pushes back on a correct answer, or present a weak plan as promising. Anthropic’s “constitutional” approach, which trains against written principles as well as preferences, and the published behaviour specifications of several companies, are attempts to name what the model should aim at besides approval.
The strongest objection
Who decides what is good for the user, if not the user? Socrates’ distinction assumes an expert who knows better than the people being served, and a technology company claiming to know what is good for a billion people is exactly the kind of paternalism many would reject. A model that refuses to agree, lectures or withholds may be worse than one that pleases.
What it means today
The objection is serious, and the answer is not paternalism but honesty. A doctor does not overrule the patient; she tells the truth and lets the patient decide. For organisations, this is a practical issue. An assistant that flatters employees’ drafts, confirms managers’ assumptions and agrees with whatever plan it is shown is worse than useless for decisions, because it adds false confidence. Leaders should test assistants on whether they disagree when they should, reward that behaviour in how they are configured, and be suspicious of any tool, or any colleague, that never says no.
9. Who owns what the machine learned?
The idea in plain terms
A language model is built from the writing of millions of people who were not asked and are not paid. Its makers say it learned from that writing, as any reader does. Many of the writers say it took their work and now competes with them. The question is what, if anything, the builders owe the people whose words made the model possible.
The tradition
John Locke, in his Second Treatise of Government (1689), argued that people come to own things by mixing their labour with what nature provides, provided that “enough, and as good” is left for others. Copyright law grew from a narrower bargain, first set out in Britain’s Statute of Anne (1710): authors receive a limited monopoly over their expression, to encourage them to create, after which their works pass into a public domain that everyone may use. Crucially, copyright protects expression, not ideas or facts; anyone may learn from a book. A different tradition, developed by the political economist Elinor Ostrom, who won the Nobel Prize in economics in 2009, studied commons: shared resources such as fisheries and pastures that communities managed sustainably for centuries through rules about who may take what. Her work showed that commons are not doomed to be overused, but they survive only when those who draw on them also sustain them.
Where it shows up
The US court ruling in 2025 drew a line between learning and taking: training on lawfully acquired books was transformative, like a reader learning from them, but keeping pirated copies was not, and the resulting settlement cost $1.5 billion.23 The lawsuit by The New York Times turns on whether a model that can reproduce and summarise journalism substitutes for it. The licensing deals between AI companies and publishers are an attempt to turn an unpaid commons into a market. And the open web itself, the commons the models were trained on, is changing in response: many sites now block AI crawlers, and the incentive to publish freely falls if readers get answers without visiting the source.
The strongest objection
Every writer learned from others without paying them. Human culture is built on imitation, influence and the free use of ideas. If learning from published work required permission, no one could think. Treating machine learning differently from human learning, the argument goes, protects incumbents at the expense of a technology that benefits everyone.
What it means today
The objection explains why training has so far been treated as lawful learning in the United States. But Ostrom’s insight points to the economic problem underneath the legal one. If AI answers draw readers away from the writers, journalists and forums whose work they depend on, those sources will produce less, and future models will have less to learn from. A commons that is only drawn on will be depleted. For organisations, the immediate lessons are practical: know where your models’ data came from, respect licences on the data you add, and recognise that your own documents, once used to train or prompt a system, become part of what it can reveal.
Bringing the threads together
The large language model began as a bet against the founding idea of its field. Where the Dartmouth proposal assumed intelligence could be described, the model learned what no one could describe, from the traces people had left in writing. That is why it can do so much (Polanyi’s tacit knowledge, absorbed at scale) and why it fails as it does (patterns without a guaranteed tie to truth). The rest follows. Its answers are testimony we cannot fully check, so trust must be calibrated by task. Its fluency invites us to see a mind, so honesty about what it is becomes a design obligation. Its training on approval pulls it toward flattery, so its makers and users must decide what it should aim at instead. Its competence erodes the skills needed to catch its errors, so organisations must decide which skills to keep. It is built from a commons it does not sustain, so the terms of its learning are an economic question as much as a legal one. And because it cannot be responsible, the people who deploy it are.
The machine that answers
Turing thought the question of whether machines can think would come to seem less interesting once machines could converse. In one sense he was right: most people using language models do not care whether they think. In another sense he was wrong. The arrival of machines that answer has made an older question urgent for every organisation. Not “can it think?” but “when should we believe it, and who answers if we were wrong to?”
The history suggests a few working principles. Expect capability to keep improving and prices to keep falling, and do not over-invest in workarounds for this year’s weaknesses. Map the jagged frontier for your own work by testing, not by impression. Measure quality on the cases that matter most, not on volume. Keep a person accountable for every use, with the skill and authority to override the machine. And remember that the most persuasive thing about these systems, their fluency, is the thing that tells you least about whether they are right.
Selected bibliography
- Lovelace, Ada. “Notes by the Translator” to L. F. Menabrea, “Sketch of the Analytical Engine.” Scientific Memoirs 3 (1843).
- Leibniz, Gottfried Wilhelm. Writings on the characteristica universalis, c. 1677–1686.
- Newell, Allen, and Herbert A. Simon. “Computer Science as Empirical Inquiry: Symbols and Search.” Communications of the ACM 19, no. 3 (1976): 113–126.
- Minsky, Marvin, and Seymour Papert. Perceptrons. MIT Press, 1969.
- Shannon, Claude E. “A Mathematical Theory of Communication.” Bell System Technical Journal 27 (1948).
- Halevy, Alon, Peter Norvig and Fernando Pereira. “The Unreasonable Effectiveness of Data.” IEEE Intelligent Systems 24, no. 2 (2009): 8–12.
- Mikolov, Tomas, et al. “Efficient Estimation of Word Representations in Vector Space.” arXiv:1301.3781 (2013).
- Hoffmann, Jordan, et al. “Training Compute-Optimal Large Language Models.” arXiv:2203.15556 (2022).
- Bai, Yuntao, et al. “Constitutional AI: Harmlessness from AI Feedback.” arXiv:2212.08073 (2022).
- Lewis, Patrick, et al. “Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks.” NeurIPS (2020).
- Plato. Gorgias. c. 380 BCE.
- Locke, John. Second Treatise of Government, chapter V, “Of Property.” 1689.
- Ostrom, Elinor. Governing the Commons. Cambridge University Press, 1990.
- European Union. Regulation (EU) 2024/1689 (Artificial Intelligence Act).
- Turing, A. M. “Computing Machinery and Intelligence.” Mind 59, no. 236 (1950): 433–460.
- McCarthy, J., M. L. Minsky, N. Rochester and C. E. Shannon. “A Proposal for the Dartmouth Summer Research Project on Artificial Intelligence.” 1955. Reprinted in AI Magazine 27, no. 4 (2006).
- Weizenbaum, Joseph. Computer Power and Human Reason: From Judgment to Calculation. W. H. Freeman, 1976.
- Lighthill, James. “Artificial Intelligence: A General Survey.” Science Research Council, 1973.
- Rumelhart, D. E., G. E. Hinton and R. J. Williams. “Learning Representations by Back-Propagating Errors.” Nature 323 (1986): 533–536.
- Sutton, Rich. “The Bitter Lesson.” 13 March 2019. incompleteideas.net
- Vaswani, Ashish, et al. “Attention Is All You Need.” Advances in Neural Information Processing Systems 30 (2017). arXiv:1706.03762.
- Brown, Tom B., et al. “Language Models Are Few-Shot Learners.” arXiv:2005.14165 (2020).
- Kaplan, Jared, et al. “Scaling Laws for Neural Language Models.” arXiv:2001.08361 (2020).
- Ouyang, Long, et al. “Training Language Models to Follow Instructions with Human Feedback.” arXiv:2203.02155 (2022).
- Bender, Emily M., Timnit Gebru, Angelina McMillan-Major and Shmargaret Shmitchell. “On the Dangers of Stochastic Parrots: Can Language Models Be Too Big?” FAccT (2021).
- Brynjolfsson, Erik, Danielle Li and Lindsey R. Raymond. “Generative AI at Work.” NBER Working Paper 31161 (2023); Quarterly Journal of Economics 140 (2025).
- Dell’Acqua, Fabrizio, et al. “Navigating the Jagged Technological Frontier.” Harvard Business School Working Paper 24-013 (2023).
- Challapally, Aditya, et al. The GenAI Divide: State of AI in Business 2025. MIT NANDA, 2025.
- Epoch AI. “LLM Inference Price Trends.” 2025. epoch.ai
- Mata v. Avianca, Inc., 678 F. Supp. 3d 443 (S.D.N.Y. 2023).
- Moffatt v. Air Canada, 2024 BCCRT 149.
- Searle, John R. “Minds, Brains, and Programs.” Behavioral and Brain Sciences 3, no. 3 (1980): 417–457.
- Wittgenstein, Ludwig. Philosophical Investigations. 1953.
- Hume, David. An Enquiry Concerning Human Understanding, Section X, “Of Miracles.” 1748.
- Reid, Thomas. An Inquiry into the Human Mind on the Principles of Common Sense. 1764.
- Hardwig, John. “Epistemic Dependence.” Journal of Philosophy 82, no. 7 (1985): 335–349.
- Frankfurt, Harry G. On Bullshit. Princeton University Press, 2005 (first published 1986).
- Hicks, Michael Townsen, James Humphries and Joe Slater. “ChatGPT Is Bullshit.” Ethics and Information Technology 26 (2024).
- Polanyi, Michael. The Tacit Dimension. University of Chicago Press, 1966.
- Autor, David. “Polanyi’s Paradox and the Shape of Employment Growth.” NBER Working Paper 20485 (2014).
- Bainbridge, Lisanne. “Ironies of Automation.” Automatica 19, no. 6 (1983): 775–779.
- Dennett, Daniel C. The Intentional Stance. MIT Press, 1987.
- Matthias, Andreas. “The Responsibility Gap: Ascribing Responsibility for the Actions of Learning Automata.” Ethics and Information Technology 6 (2004): 175–183.
- Aristotle. Nicomachean Ethics, Books II and III.
Research limitations
This essay covers a field that changes monthly, and some details will date quickly; it reflects published information up to October 2026. The Dartmouth conjecture is quoted from reproductions of the 1955 proposal, which differ slightly in wording across copies. Weizenbaum’s secretary anecdote is his own account, reported through secondary sources. The ChatGPT growth figure is a UBS estimate from web-traffic data, not a company figure; the 800 million weekly users is OpenAI’s own statement from October 2025, and later figures circulating in secondary sources were not verified. The customer support figures come from the working paper version of Brynjolfsson, Li and Raymond; the published version reports a 15 percent average. The consultant study is a working paper. The MIT NANDA figure comes from a small, preliminary study reported mostly through coverage rather than the original report. Klarna’s figures are company claims, and the chief executive’s later remarks are reported through press coverage of a Bloomberg interview. The DeepSeek cost claims were disputed and are not relied on here. Descriptions of OpenAI’s 2023 board crisis are limited to widely reported facts and do not attempt to judge the motives of anyone involved. Decisions in the decisions box are judged by the author on the evidence cited, with an attempt to separate what could be known at the time (the process grade) from what happened (the call). The perceptron press quotation comes from a wire report reproduced in secondary sources. Jelinek’s remark about linguists is widely repeated in several versions and is presented as attributed, not verified. The “We have no moat” document was never confirmed as an official Google position. The account of the Watson Health project relies on contemporary press reports of a university audit and IBM’s response, and does not judge any individual. The Anthropic settlement figures come from press reports of the court’s approval; the New York Times case was unresolved at the time of writing. The advertising test is described from reports of OpenAI’s announcement. The philosophical connections to Leibniz, Lovelace, Turing, Searle, Wittgenstein, Hume, Reid, Hardwig, Frankfurt, Polanyi, Bainbridge, Dennett, Plato, Locke, Ostrom, Matthias and Aristotle are the author’s interpretation; their works are paraphrased, apart from short, attributed phrases.
Footnotes
-
A. M. Turing, “Computing Machinery and Intelligence,” Mind 59, no. 236 (October 1950): 433–460, first sentence. ↩ ↩2 ↩3
-
J. McCarthy, M. L. Minsky, N. Rochester and C. E. Shannon, “A Proposal for the Dartmouth Summer Research Project on Artificial Intelligence” (31 August 1955); reprinted in AI Magazine 27, no. 4 (2006). See also Wikipedia, “Dartmouth workshop”. ↩
-
UPI wire report of 7 July 1958, as carried in The New York Times, 8 July 1958; quoted in Wikipedia, “Perceptron”. ↩
-
Akira Ishikawa’s 1993 account of the project, summarised in Wikipedia, “Fifth Generation Computer Systems”. ↩
-
Joseph Weizenbaum, Computer Power and Human Reason (1976), as quoted in Wikipedia, “ELIZA”. ↩
-
David E. Rumelhart, Geoffrey E. Hinton and Ronald J. Williams, “Learning representations by back-propagating errors,” Nature 323 (1986): 533–536. ↩
-
Alon Halevy, Peter Norvig and Fernando Pereira, “The Unreasonable Effectiveness of Data,” IEEE Intelligent Systems 24, no. 2 (March/April 2009): 8–12; see the Google Research blog. ↩
-
“Watson-based cancer project paused after running aground,” Engadget, 20 February 2017; MedCity News, February 2017, including IBM’s response. ↩
-
Rich Sutton, “The Bitter Lesson,” 13 March 2019, incompleteideas.net, first sentence. ↩
-
Ashish Vaswani et al., “Attention Is All You Need,” arXiv:1706.03762 (June 2017). ↩
-
“OpenAI has released the largest version yet of its fake-news-spewing AI,” MIT Technology Review, 29 August 2019, technologyreview.com. ↩
-
Jared Kaplan et al., “Scaling Laws for Neural Language Models,” arXiv:2001.08361 (January 2020). ↩
-
Jordan Hoffmann et al., “Training Compute-Optimal Large Language Models,” arXiv:2203.15556 (March 2022); DeepMind blog, 12 April 2022. ↩
-
“GitHub Copilot is generally available to all developers,” GitHub blog, 21 June 2022. ↩
-
Long Ouyang et al., “Training language models to follow instructions with human feedback,” arXiv:2203.02155 (March 2022), abstract. ↩
-
OpenAI, “Sycophancy in GPT-4o,” 29 April 2025, as reported by TechCrunch. ↩ ↩2
-
“ChatGPT sets record for fastest-growing user base – analyst note,” Reuters, 2 February 2023, reporting a UBS study using Similarweb data; see for example Inquirer Business. ↩
-
Bing Search Blog, “The new Bing & Edge – Updates to Chat,” 17 February 2023, blogs.bing.com. ↩
-
“Google shares drop $100 billion after its new AI chatbot makes a mistake,” NPR, 9 February 2023, npr.org. ↩
-
“Google pauses Gemini’s ability to generate AI images of people after diversity errors,” TechCrunch, 22 February 2024; on the chief executive’s memo, Quartz. ↩
-
Mata v. Avianca, Inc., 678 F. Supp. 3d 443 (S.D.N.Y. 22 June 2023); see Wikipedia, “Mata v. Avianca, Inc.”, and the affidavit as reported by ABC7. ↩
-
Moffatt v. Air Canada, 2024 BCCRT 149 (14 February 2024), civilresolutionbc.ca; see also the summary by McCarthy Tétrault. ↩
-
“Judge approves record $1.5 billion AI copyright settlement involving Anthropic,” JURIST, July 2026; on the June 2025 fair-use ruling, Bartz v. Anthropic PBC (N.D. Cal.). ↩ ↩2
-
“Nvidia’s $589 Billion DeepSeek Rout Is Largest in Market History,” Bloomberg, 27 January 2025, bloomberg.com. ↩
-
Epoch AI, “LLM inference prices have fallen rapidly but unequally across tasks,” 2025, epoch.ai. ↩
-
“OpenAI teams up with SoftBank and Oracle on $500B data center project,” TechCrunch, 21 January 2025. ↩
-
“OpenAI to start testing ChatGPT ads across Free and Go tiers,” SiliconANGLE, 16 January 2026. ↩
-
“OpenAI completes its for-profit recapitalization,” TechCrunch, 28 October 2025, techcrunch.com; Al Jazeera. ↩
-
Erik Brynjolfsson, Danielle Li and Lindsey R. Raymond, “Generative AI at Work,” NBER Working Paper 31161 (April 2023), nber.org; published in Quarterly Journal of Economics 140 (2025): 889–942. ↩
-
Fabrizio Dell’Acqua et al., “Navigating the Jagged Technological Frontier: Field Experimental Evidence of the Effects of AI on Knowledge Worker Productivity and Quality,” Harvard Business School Working Paper 24-013 (September 2023); summarised by co-author Ethan Mollick, “Centaurs and Cyborgs on the Jagged Frontier”, and The Harvard Crimson. ↩
-
Coverage of MIT NANDA, The GenAI Divide: State of AI in Business 2025, for example The Register, 18 August 2025. ↩
-
On the February 2024 announcement and the 2025 reversal, see Computing and Entrepreneur, reporting the chief executive’s interview with Bloomberg. ↩
How it evolved
The arc
- 1843
Ada Lovelace writes that Babbage’s Analytical Engine can do only “whatever we know how to order it to perform.”
- 1950
Alan Turing asks “Can machines think?” in Mind and proposes replacing the question with an imitation game.
- 1956
The Dartmouth summer project gives “artificial intelligence” its name, on the conjecture that intelligence can be described precisely enough to be simulated.
- 1958
Frank Rosenblatt’s perceptron, a machine that learns from examples, is demonstrated for the US Navy amid extravagant press claims.
- 1966
Joseph Weizenbaum’s ELIZA imitates a therapist with simple pattern-matching. Users confide in it anyway.
- 1969
Minsky and Papert’s Perceptrons proves the limits of single-layer networks. Neural network research goes quiet for over a decade.
- 1973
The Lighthill report in Britain judges that AI has failed to meet its promises. Funding falls; the first “AI winter” sets in.
- 1980s
Expert systems encode specialists’ rules for business. They prove expensive to maintain and brittle at the edges.
- 1982
Japan launches the ten-year Fifth Generation Computer Systems project to build machines for logical inference.
- 1986
Rumelhart, Hinton and Williams popularise backpropagation, the method for training many-layered neural networks.
- 2009
Google researchers publish “The Unreasonable Effectiveness of Data,” urging the field to follow the data rather than elegant theories.
- 2011
IBM’s Watson wins Jeopardy! IBM turns it into a business aimed at medicine, with disappointing results.
- 2012
A deep neural network, AlexNet, wins the ImageNet competition by a wide margin. Learning from data overtakes hand-built features.
- 2015
OpenAI is founded as a nonprofit research laboratory, partly to keep advanced AI from being controlled by a single company.
- 2017
Google researchers publish “Attention Is All You Need,” introducing the Transformer.
- 2019
OpenAI withholds the full GPT-2 over misuse concerns, releases it in stages, and creates a capped-profit company backed by Microsoft.
- 2020
GPT-3, with 175 billion parameters, shows that a single model can attempt many tasks from a few examples in a prompt.
- 2021
GitHub Copilot previews AI code completion, the first mass-market product built on a large language model.
- 2022
OpenAI releases ChatGPT on 30 November as a research preview. An estimated 100 million people use it within two months.
- 2023
GPT-4, Google’s Bard and Meta’s openly downloadable Llama models arrive. A New York court sanctions lawyers who filed AI-invented cases.
- 2024
“Reasoning” models that work through a problem before answering appear. A Canadian tribunal holds an airline liable for its chatbot’s advice.
- 2025
DeepSeek’s open R1 model triggers a record one-day fall in Nvidia’s market value. Agents that write and test code go mainstream. Anthropic agrees a $1.5 billion settlement with authors. OpenAI becomes a public benefit corporation controlled by a foundation.
- 2026
OpenAI begins testing advertising in ChatGPT’s free tiers, as the cost of the frontier pushes the industry toward new ways to pay for it.
Left open
Questions to sit with
- Which of the answers you relied on this week could you actually have checked, and which did you accept because they sounded right?
- If a model is right ninety-five times in a hundred, what kind of work can afford the other five?
- When an assistant drafts the analysis and you approve it, whose judgement is the decision?
- What skills in your organisation are learned by doing the very tasks you are now automating?
- Should a machine that cannot be held responsible ever be allowed to speak in your company’s voice without a person behind it?
Follow the thread
Where this essay connects
- Overconfidence and CalibrationHow minds decide
- Risk and UncertaintyHow minds decide
- The Inside View and the Outside ViewHow minds decide
- The Mind Beyond the HeadHow minds decide
- Trusting the Machine Too MuchHow minds decide
- We Know More Than We Can TellHow minds decide
- Legibility and MētisHow systems shape choices
- The Knowledge No One HoldsHow systems shape choices
- The Remedy That Is Also a PoisonHow systems shape choices
- When a Measure Becomes a TargetHow systems shape choices
- Why Good Management FailsHow systems shape choices
- Practical WisdomThe one who decides
Shrikant Kumar. “The Machine That Answers.” Essay on Large Language Models, Telos, published 3 March 2024, updated 22 October 2026. https://shrikantk.com/blog/the-machine-that-answers/